
DATA ENGINEERING SERVICES
Data engineering for analytics and AI
Our data engineering teams build and operate tested pipelines that turn raw sources into reliable data for reporting, applications and AI.
- A medallion architecture, so quality and structure improve at each layer
- Every transition is code: tested, versioned, and orchestrated
- Batch and streaming feed one architecture, so data stays consistent
From raw sources to trusted data.
Quality and structure improve at each stage, and every consumer knows what to expect. Each transition is code: tested, versioned, and orchestrated, with data quality checks between layers so problems are caught before they propagate. Batch and streaming feed the same architecture, so real-time and historical data stay consistent. Quality and lineage on every table are governed through data management and governance, and the work can run with a Databricks-based lakehouse or your current stack. Each transition is code: tested, versioned, and orchestrated. Batch and streaming feed the same medallion layers, so real-time and historical data stay consistent.
Source
Operational systems, files, streams, and APIs, raw as produced. Where the data lands.
Bronze
Ingested, immutable landing: raw but captured and replayable. Nothing lost, everything reproducible.
Silver
Cleaned, conformed, and deduplicated: trustworthy, joined, business-conformed. Data you can join and trust.
Gold
Aggregated and modeled for consumption: BI-, ML-, and product-ready. Served, documented, and governed.
Consumers
BI, ML, reverse ETL, and applications, all on governed, documented tables. Every consumer knows what to expect.
Quality gates
Data quality checks between layers, so problems are caught before they propagate. Bad data fails the build, not the dashboard.
Turn raw source data into a dependable, ready-to-use asset.
What our data engineering services deliver.
- Ingestion pipelines from operational systems, files, APIs, and streams, with CDC where needed.
- Transformation layer in dbt and Spark, modeling raw data into conformed, documented tables.
- Orchestration with Airflow or Dagster: scheduled, dependency-aware, and observable.
- Data quality tests between layers, so bad data fails the build instead of the dashboard.
- Documentation and lineage, so every table has an owner, a definition, and a traceable source.
From source assessment to reliable operations.
Model
Define what consumers need in gold, worked backward to source.
Build
Build ingestion and the medallion layers as tested, version-controlled code.
Orchestrate
Schedule with dependency-aware orchestration and failure handling.
Test
Run quality checks, contracts, and CI continuously on every change.
Operate
Monitor, alert, and cost-tune, run by us or handed to your team.
Tools that fit your platform.
A representative stack by layer. We work across lakehouse platforms and reuse what is sound rather than replacing it wholesale.
We build cloud-native on your platform, whether that is Databricks, Snowflake, BigQuery, or your current stack.
From brittle, silent pipelines to reliable, tested loads.
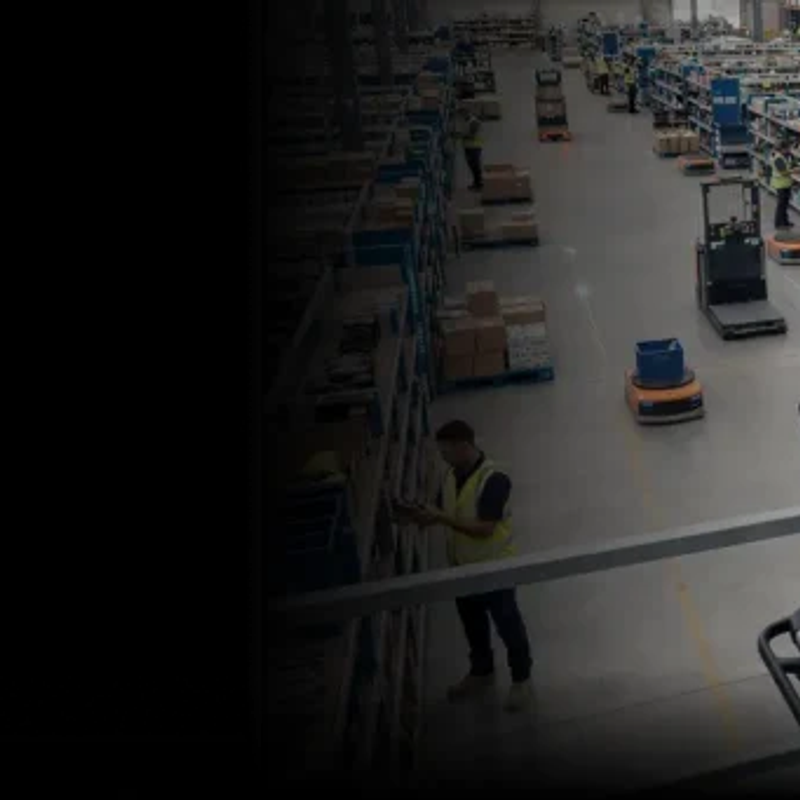
Challenge: Product data sat fragmented across Stibo, MSSQL, and warehouse systems, and stock visibility lagged by more than six hours, slowing procurement and sales across a 300,000+ product catalog.
Approach: Rebuilt on a medallion architecture with dbt, Airflow, and quality tests between layers.
Result: Azure Data Factory pipelines cut the stock lag from 6+ hours to under one, with tested transformations and lineage on every table. Read the story.
The layer that powers everything downstream.
Data Management and Governance
The catalog, lineage, and quality that keep pipelines accountable.
Data Streaming and Real-Time Analytics
Real-time data feeding the same medallion layers as batch.
Data Democratization
The self-service that gold-layer tables and a semantic layer make possible.
Databricks
The lakehouse foundation we build Spark, Delta, and Unity Catalog pipelines on.
Dedicated Teams
The senior pod that builds and operates your pipelines alongside you.
Data and Analytics Services
The parent practice this engineering layer belongs to.
What data leaders ask us first.
Mostly ELT on modern lakehouse platforms: load raw, then transform in-warehouse with dbt and Spark for scalability and lineage. We use ETL where a source or compliance constraint requires it.
Yes. We feed both into the same medallion layers so real-time and historical data stay consistent, avoiding the classic split-brain between two stacks.
Yes. We build cloud-native on Databricks, Snowflake, BigQuery, or your current stack, reusing what is sound rather than replacing it wholesale.

Engineer the pipelines that turn your raw data into a dependable, ready-to-use asset.
A medallion architecture built as tested, version-controlled code, with quality checks between every layer.